What is GLM-5.3-Flash (GLM 5.3 Flash)?
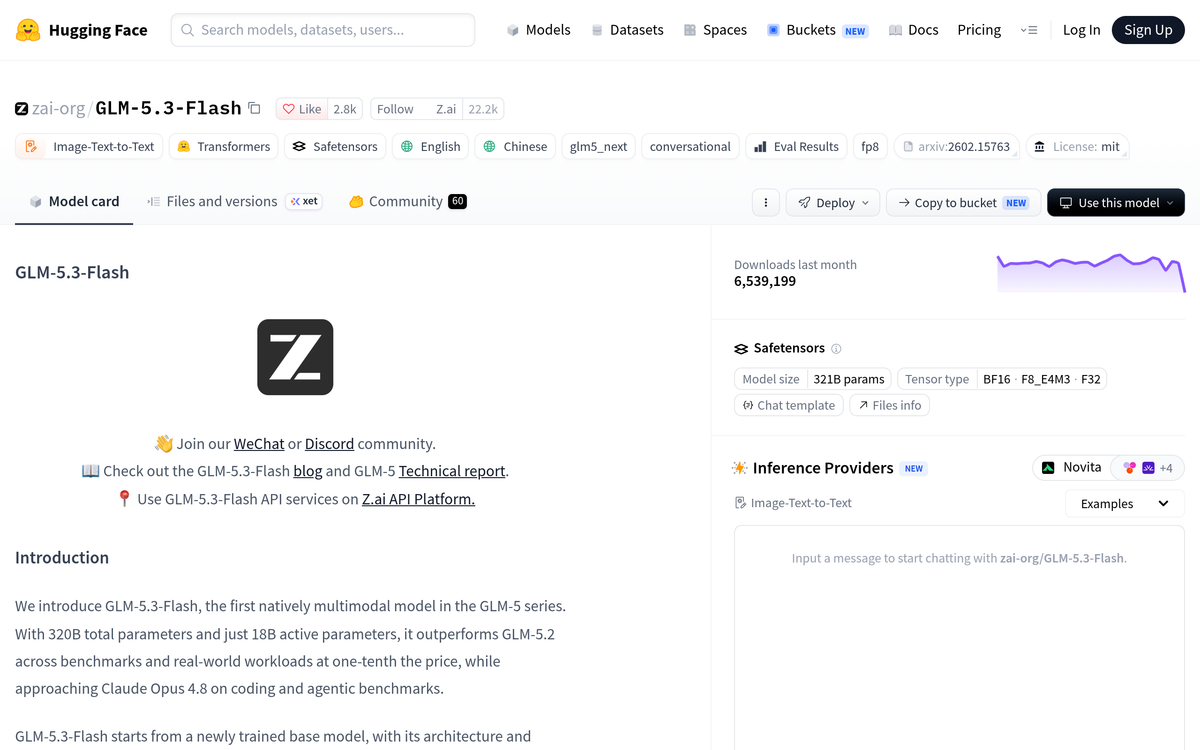
GLM-5.3-Flash (commonly searched as GLM 5.3 Flash) is the first natively multimodal flagship model in the Zhipu AI GLM series (Z.ai). Built on a Mixture-of-Experts (MoE) architecture with 320B total parameters and just 18B active parameters, it achieves frontier-grade reasoning, coding, and vision understanding while reducing inference costs by nearly 90% compared to dense alternatives.
For developers exploring open-source models, see also our AI Chat tools directory and our review of Claude.
Key Capabilities
- Native Multimodality — trained from the ground up on a 30T-token multimodal corpus, unifying text, vision, and document analysis.
- Ultra-Long 1M Context Window — supports up to 1,048,576 tokens with a hybrid sparse and linear attention architecture, eliminating context degradation.
- Reasoning Effort Control — allows developers to control thinking depth via the
reasoning_effortparameter (low,high, ormax). - High Efficiency & Low Latency — 18B active parameters mean fast time-to-first-token and cost-effective self-hosting on standard GPU setups.
- Wide Framework Support — day-0 deployment recipes for vLLM, SGLang, KTransformers, and Cloudflare Workers AI (
@cf/zai-org/glm-5.3-flash).
Pricing and API Access
- Self-Hosting — open weights in FP8 and BF16 available on Hugging Face and ModelScope.
- Cloudflare Workers AI — available serverless at $0.15 / M input tokens and $0.50 / M output tokens ($0.03 / M cached tokens).
- Z.ai API Platform — available via OpenAI-compatible endpoints with full function calling support.
GLM 5.3 Flash vs Other Frontier Models
- vs DeepSeek V3 / Qwen 2.5 — GLM 5.3 Flash combines 1M long-context multimodal understanding with MoE efficiency, competing closely with Claude Opus-tier performance on agentic coding evals.
- vs Closed Frontier Models — delivers near-frontier reasoning speed for production pipelines at a fraction of the token cost.
Frequently Asked Questions
Is GLM 5.3 Flash open weights?
Yes. Weights are openly downloadable on Hugging Face and ModelScope for research and commercial applications subject to Zhipu's open license agreement.
How many parameters does GLM-5.3-Flash activate per token?
It activates only 18B parameters per token out of 320B total parameters, giving it the speed and memory profile of a lightweight model with the knowledge capacity of a massive model.